You run a program that processes a large file. The first execution takes several seconds. You run exactly the same command again, and suddenly the result appears almost immediately.
The code did not change. The file did not change. Your SSD did not suddenly become five times faster.
One thing probably changed: the data no longer had to be fetched from the storage device.
Linux used available RAM as the page cache.
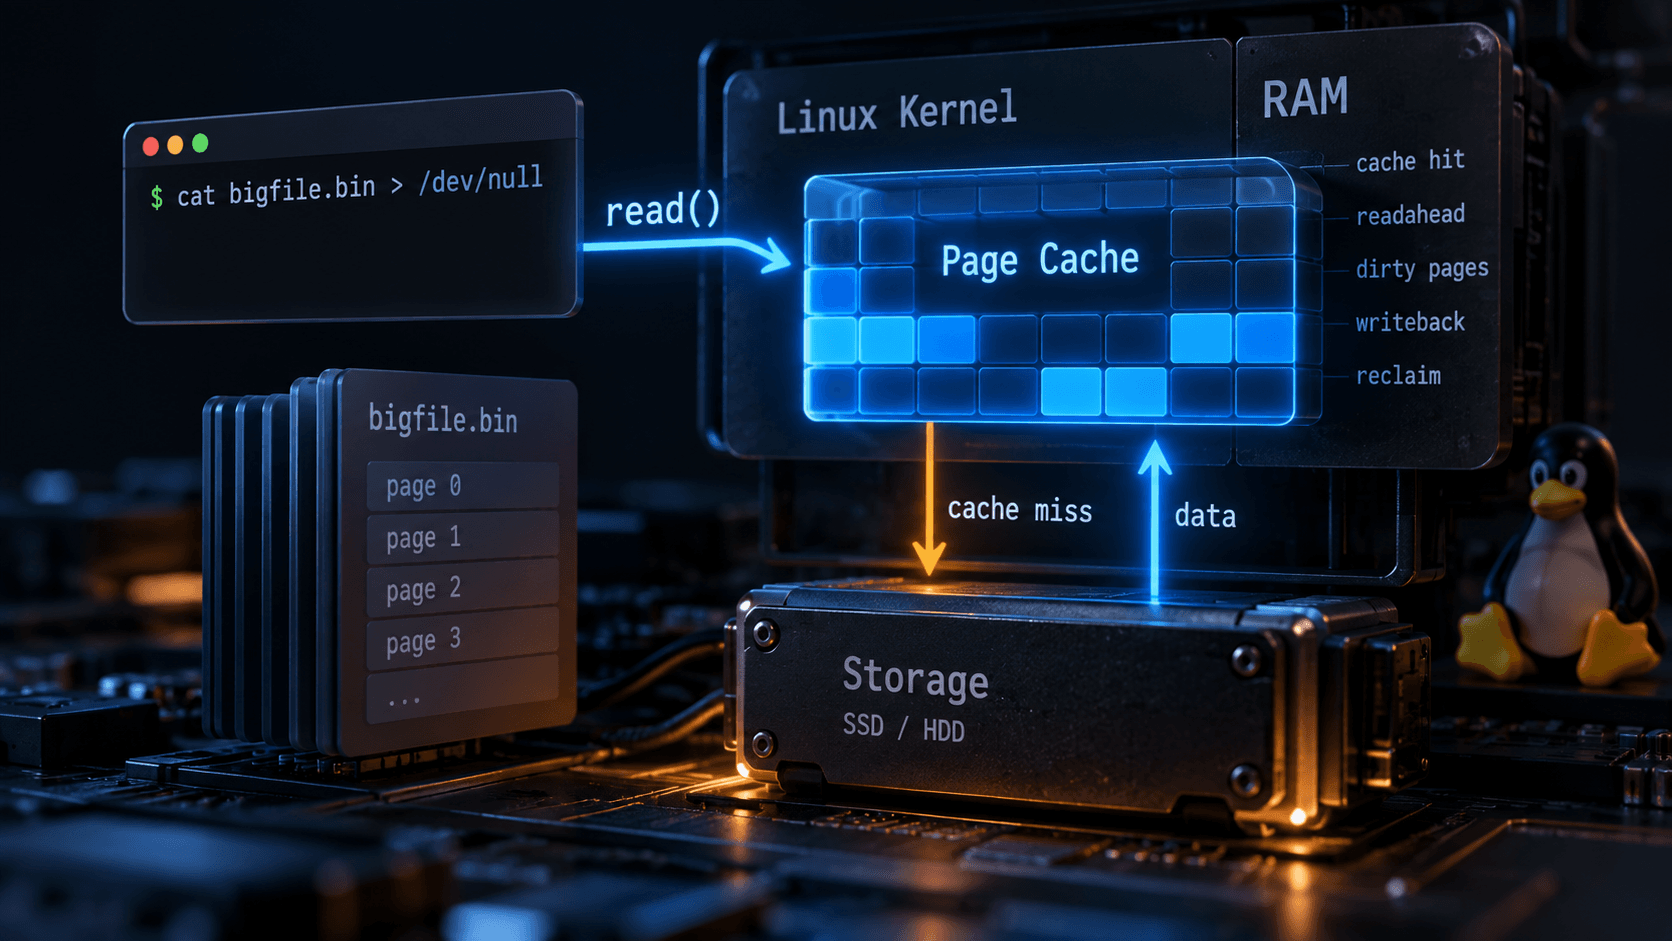
It is one of those mechanisms that operates constantly but is easy to forget about. You call read(), see a file being read, and intuitively think: disk. In reality, normal buffered I/O on Linux goes through the page cache. If the required data is already in memory, the kernel can satisfy the read without fetching it from storage again.
The same mechanism is involved in read(), file-backed mmap(), readahead, dirty pages, and writeback. It also explains why a server with 32 GB of RAM may report very little memory as free without actually being short on memory.
The page cache is not an optional optimization bolted onto the filesystem. It is a central part of the normal Linux I/O path.
What Does Linux Actually Cache?
int fd = open("database.bin", O_RDONLY);

char buf[4096];
read(fd, buf, sizeof(buf));
The kernel first determines whether the requested part of the file is already available in the page cache. If it is, you have a cache hit. If not, you have a cache miss: Linux initiates I/O, retrieves the data from storage, and populates the page cache before read() copies it into the process buffer.
first read:
process -> read() -> page cache MISS -> storage
                                      |
                                      v
                                  page cache
                                      |
                                      v
                                   process

later read:
process -> read() -> page cache HIT -> process
That does not mean every second read will be faster. The data may have been evicted, the file may be larger than available memory, another workload may have created memory pressure, or the filesystem and I/O mode may take a different path.
Reading a file does not necessarily mean performing physical I/O against the storage device.
The Page Cache Is Not a Second Copy of the Entire File
The kernel manages cached file contents in smaller units. In current kernel terminology, the core abstraction used by the page cache is a folio. A folio may contain one or more memory pages.
The common explanation that the page cache stores files in 4 KB chunks is useful as an introductory model, but it is not a universal description of modern Linux. A base page is commonly 4 KiB on many systems, but the page cache should not be understood as permanently restricted to elements of that exact size.
A better mental model is: the kernel can keep specific ranges of file contents in RAM and reuse them on later accesses.
Why read() Still Copies Data
The page cache is managed by the kernel. The buffer supplied to read() belongs to the process.
storage
   |
   v
page cache
   |
   | copy_to_user()
   v
userspace buffer
When the data is already cached, the cost of accessing storage disappears, but the kernel still has to copy the data into the process buffer.
This is where page cache connects to file-backed mmap(). Both interact with the same fundamental file-cache layer, but expose data to the process differently.
Readahead — Linux Reads More Than You Asked For
If an application reads a large file sequentially, the kernel can recognize the access pattern. Linux implements readahead, allowing it to start fetching upcoming file data before the application explicitly asks for it.
application needs:
[A]

kernel may fetch:
[A][B][C][D]
   ^^^^^^^^^
    readahead
By the time the application reaches B, the data may already be waiting in the page cache. This is also why careless I/O benchmarks can be misleading: two runs may compare not only implementations, but also cold cache vs warm cache.
Random Access Changes the Equation
Readahead works best when future accesses can be predicted. Sequential access is predictable; random access is not.
posix_fadvise(fd, 0, 0, POSIX_FADV_SEQUENTIAL);
posix_fadvise(fd, 0, 0, POSIX_FADV_RANDOM);
These calls provide advice about the expected access pattern. They are not commands forcing the kernel into one exact strategy. Other options include POSIX_FADV_WILLNEED, POSIX_FADV_DONTNEED, and POSIX_FADV_NOREUSE.
Writes Use the Page Cache Too
With normal buffered writes, modified data may first exist in memory and become dirty.
process
   |
   | write()
   v
page cache
   |
   | dirty
   v
[RAM]

... later ...

writeback
   |
   v
storage
Dirty means that the version in RAM is newer than the corresponding contents on persistent storage. This is one reason write() may return long before the data physically reaches the storage device.
A successful write() alone is not a general guarantee that the data would survive an immediate power failure.
Dirty, Writeback, and Cached — You Can Observe Them
grep -E 'MemFree|MemAvailable|Cached|Dirty|Writeback' /proc/meminfoCached includes memory associated with file caching. Dirty represents memory waiting to be written, while Writeback represents data currently being written back.
The distinction between MemFree and MemAvailable is particularly important. The latter attempts to estimate how much memory applications could use without the system having to swap.
“Linux Ate All My RAM”
A small free value does not automatically indicate a problem. RAM that stores nothing does not make the machine faster. If applications do not currently need that memory, using it to retain data that may soon be accessed again is useful.
The crucial property is that clean file cache is reclaimable. When applications need more memory, the kernel can reclaim RAM occupied by clean cached data because another copy still exists on backing storage.
Reclaim — When Cache Has to Make Room
The page cache cannot grow forever at the expense of everything else. Under memory pressure, the kernel performs reclaim.
Clean file-backed data can be discarded because the same contents still exist on storage. Dirty data are different: they cannot simply be thrown away because RAM may contain the only current version of the modifications.
The page cache uses RAM while keeping that memory available for more valuable uses when pressure appears.
Seeing the Cache Effect Without Guessing
dd if=/dev/urandom of=test.bin bs=1M count=1024 status=progress
/usr/bin/time -v cat test.bin > /dev/null
/usr/bin/time -v cat test.bin > /dev/null
On a system with enough available memory, the second execution may be faster because much of the file may already reside in the page cache. The exact result depends on available RAM, previous system activity, filesystem, storage hardware, competing processes, file size, and cache state.
drop_caches — Useful Tool, Bad Ritual
sync
echo 3 | sudo tee /proc/sys/vm/drop_caches
Linux exposes drop_caches, but it is a system-wide operation, not a precise “clear only my benchmark cache” button. Kernel documentation warns that using it outside testing and debugging may cause performance problems because the system has to rebuild discarded cache and metadata.
For a specific file range, posix_fadvise(..., POSIX_FADV_DONTNEED) may be more targeted, although it remains advice to the kernel.
Page Cache and mmap() — The Missing Piece
With read(), file data go through the page cache and are copied into a userspace buffer. With file-backed mmap(), the cached file contents are mapped into the process address space.
Accessing a mapped region may generate a page fault. If the required file data are already resident, servicing that fault does not necessarily require storage I/O. A page fault does not automatically mean disk I/O.
Can You Bypass the Page Cache?
Yes. Linux provides mechanisms such as O_DIRECT, allowing I/O to bypass the normal page-cache path.
But O_DIRECT does not automatically mean faster. Bypassing cache means giving up that reuse layer and often taking more responsibility for I/O management, alignment, batching, and caching strategy inside the application.
When Page Cache Helps — and When It Can Hurt
The page cache is especially useful when data are reused. A one-time scan of data much larger than memory is different: it can populate cache with data that have almost no probability of reuse while displacing entries useful to other processes.
Since Linux 6.3, POSIX_FADV_NOREUSE has meaningful page-replacement semantics. It demonstrates a more general rule: a cache is valuable when reuse exists.
Page Cache Changes How You Think About I/O
read() does not automatically mean disk. Low free RAM does not automatically mean a memory problem. A returned write() does not automatically mean durable storage. And a faster second benchmark does not automatically prove that implementation B is better.
The page cache sits directly at the boundary between memory and persistent I/O. That is why it affects filesystem performance, mmap(), RAM usage, writeback, and benchmark reliability at the same time.
Conclusion: Free RAM Should Be Doing Work
Normal buffered reads and writes, as well as file-backed mmap(), interact with the page cache. Reads may be satisfied from RAM instead of storage. Sequential workloads can benefit from readahead. Writes create dirty data that later go through writeback. Under memory pressure, clean cached data can be reclaimed because their contents still exist on backing storage.
read() does not mean “read this from disk.” It means “give me this data.” The kernel decides whether it actually has to go all the way to storage to get it.
Related Articles
- mmap — when memory-mapped I/O beats read() and write()
- Anatomy of a segfault — from the MMU through the kernel to a gdb core dump
- malloc internals — why free() doesn’t return memory to the OS
- epoll vs io_uring — when the event loop stops being enough
Technical Sources
- Linux Kernel Documentation — Page Cache
- Linux Kernel Documentation — Overview of the Linux Virtual File System
- Linux Kernel Documentation — memory reclaim
- Linux Kernel Documentation — /proc/sys/vm/, including drop_caches
- Linux man-pages — posix_fadvise(2)
- Linux man-pages — proc_meminfo(5)