DRY as a Cult — and Its Hidden Cost
“Don’t Repeat Yourself” is easily reduced to hunting similar lines. A code review asks for a shared function; the code gets shorter, but the next change needs a flag, an exception and checks across three independent modules. What became simpler?
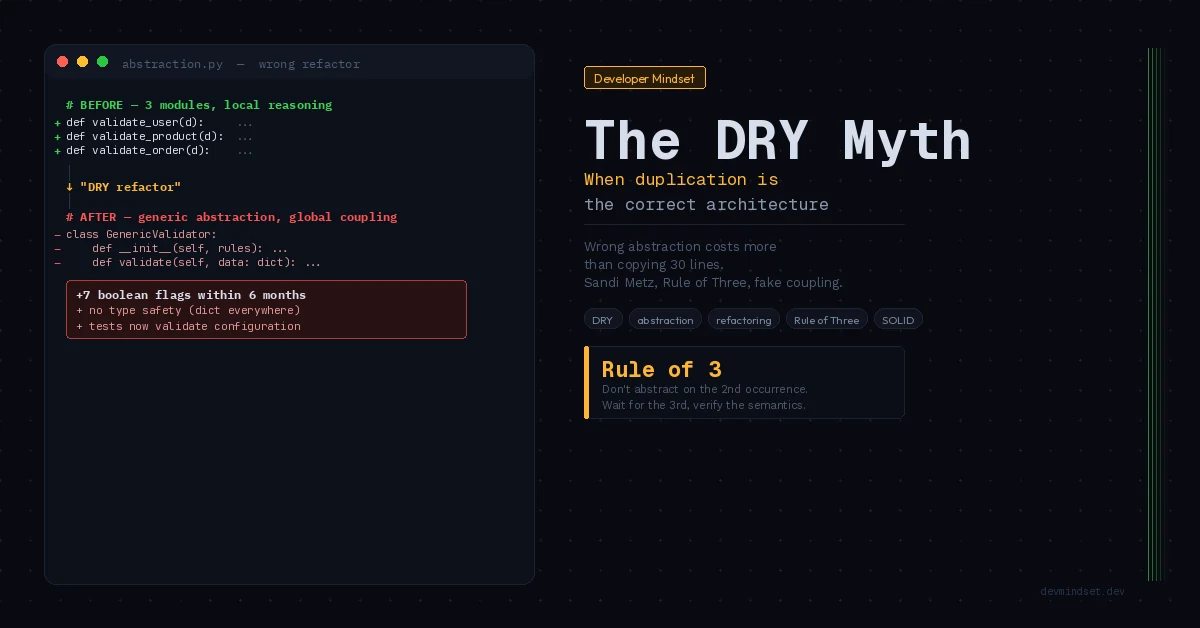
Yet it isn’t DRY that kills codebases. Premature abstraction kills codebases. Quoting Sandi Metz: “duplication is far cheaper than the wrong abstraction” — and that sentence should hang in every architecture room next to the SOLID principles, as a counterpoint.
This article dissects the moment when chasing DRY stops being engineering and becomes technical debt with non-obvious compound interest. It shows how to recognize fake duplication (incidental similarity) versus real duplication (the same domain concept repeated), and when to consciously leave 30 copied lines in three places.
The Original Context of DRY — and How It Was Twisted
Andy Hunt and Dave Thomas, in The Pragmatic Programmer (1999), formulated DRY very precisely:
“Every piece of knowledge must have a single, unambiguous, authoritative representation within a system.”
The key word: knowledge. Not code. Not syntax. Domain knowledge.
Copy the same tax rule into five places, and a change requires five consistent updates. That is a DRY problem. When similar lines describe different rules that evolve independently, a shared function may hide that distinction.
Anatomy of a Fake Abstraction
Consider a realistic scenario. An e-commerce system. Three modules with input validation functions:
# module: user_registration.py
def validate_user_data(data: dict) -> ValidationResult:
    errors = []
    if not data.get("email"):
        errors.append("Email is required")
    if len(data.get("password", "")) < 8:
        errors.append("Password too short")
    if not data.get("terms_accepted"):
        errors.append("Terms must be accepted")
    return ValidationResult(valid=not errors, errors=errors)


# module: product_creation.py
def validate_product_data(data: dict) -> ValidationResult:
    errors = []
    if not data.get("name"):
        errors.append("Name is required")
    if data.get("price", 0) <= 0:
        errors.append("Price must be positive")
    if not data.get("category_id"):
        errors.append("Category is required")
    return ValidationResult(valid=not errors, errors=errors)


# module: order_submission.py
def validate_order_data(data: dict) -> ValidationResult:
    errors = []
    if not data.get("user_id"):
        errors.append("User is required")
    if not data.get("items"):
        errors.append("Order must contain items")
    if data.get("total", 0) <= 0:
        errors.append("Total must be positive")
    return ValidationResult(valid=not errors, errors=errors)
The common error-collection mechanism could become a GenericValidator with a rule list. These examples are sketches: result types and rule classes are omitted.
class GenericValidator:
    """
    Shared mechanism; domain rules remain separate.
    """

    def __init__(self, rules: list[ValidationRule]) -> None:
        self._rules = rules

    def validate(self, data: dict) -> ValidationResult:
        errors = [
            rule.error_message
            for rule in self._rules
            if not rule.check(data)
        ]
        return ValidationResult(valid=not errors, errors=errors)


# Now usage looks like:
USER_VALIDATOR = GenericValidator([
    RequiredFieldRule("email", "Email is required"),
    MinLengthRule("password", 8, "Password too short"),
    BooleanTrueRule("terms_accepted", "Terms must be accepted"),
])
This refactor alone does not demonstrate a mistake. A rules engine can be useful. The trap begins when distinct domain policies are forced into it to preserve the shared abstraction.
Where a Shared Abstraction Adds Cost
Check these questions as requirements change:
- Do the rules still evolve independently? An email-domain rule need not change the engine. But branches saying “for users do X, for products Y” mix responsibilities.
- Does the interface preserve required types? Both examples already use
dict, so this refactor does not remove existing type safety. Replacing concrete DTOs with dictionaries just to fit a shared API would be a different issue. - How far does a change reach? Changing a shared engine requires checking its clients. A separate domain-rule change need not affect other validators.
- What do tests verify? Test accepted data and returned errors. Configuration tests are not inherently less valuable; merely restating configuration is insufficient.
Quoting Sandi Metz again: “prefer duplication over the wrong abstraction”. The pre-refactor code was readable in a single scope. Each validation function was self-contained, had full context, and could be changed without consequences elsewhere.
The Rule of Three — When the Abstraction Is Ready
The rule of three suggests checking for a recognizable pattern when another similar case appears. It gives you time to understand differences between uses.
Rule of Three is a heuristic, not a statistical law. A third occurrence provides more evidence but does not guarantee a good abstraction. Two copies of a well-understood rule may already need a shared source.
The risk of early extraction is that the next case only almost fits. Before adding a special flag, check whether the function still represents one coherent operation.
A Growing Flag List as a Warning Sign
A classic symptom of premature abstraction. A function that once did one thing now accepts a growing set of flags:
def process_order(
    order: Order,
    skip_inventory_check: bool = False,
    skip_payment: bool = False,
    is_b2b: bool = False,
    is_subscription: bool = False,
    bypass_fraud_check: bool = False,
    legacy_pricing_mode: bool = False,
    use_new_tax_calculator: bool = True,
) -> OrderResult:
    # 200 lines of branching hell
    ...
Not every flag is a design mistake, but a growing list makes valid variants harder to understand. n independent Boolean flags have 2ⁿ value combinations. That does not mean cyclomatic complexity automatically grows exponentially or every combination is a reachable path.
Consider operations named by intent, such as process_b2b_subscription_order() and process_one_off_consumer_order(). Shared steps can remain shared without a single public interface full of switches.
Decision Matrix: DRY or Duplication?
| Situation | What to check |
|---|---|
| Same business rule | Should all uses change together? If so, seek one source. |
| Similar constants, such as timeouts | The same number may represent different policies. Name each intent. |
| API contract | Keep an agreed source; client-generation choices depend on the project. |
| Validation of different entities | Share mechanisms while keeping domain rules separate. |
| Similar code, different reasons to change | Preserve independent evolution. |
| Several uses with the same semantics | A shared abstraction may reduce change cost. |
Heuristic Test: When Abstraction Is Appropriate
Before extracting shared code, ask yourself four questions:
- Will both places change for the same reason? If not — duplication is incidental, don’t extract. (Single Responsibility Principle, formulated by Robert Martin as: “a module should have one and only one reason to change”).
- Can I name this abstraction without using “Generic”, “Common”, “Util”, “Helper”, “Base”? If not — you lack a domain concept. There’s no abstraction without a name that reflects intent.
- Can I change one of the duplications without looking at the others? If yes, duplication buys you local reasoning independence. That’s value, not waste.
- Are both places in the same domain context? Sharing across bounded contexts introduces dependency. That can be deliberate, but similar names and lines do not justify it alone.
Do not count answers mechanically: “yes” to the third question supports independence. Look for shared semantics and a shared reason to change. Repetition count alone does not decide.
Concrete Example: When the Same Line of Code in Two Places Is Correct
The sketch compares module responsibilities, not a complete authentication policy. Required claims, issuer and audience validation must follow the token contract.
# auth/jwt_validator.py
def validate_jwt(token: str) -> UserClaims:
    try:
        payload = jwt.decode(token, SECRET_KEY, algorithms=["HS256"])
    except jwt.ExpiredSignatureError:
        raise AuthenticationError("Token expired")
    except jwt.InvalidTokenError as exc:
        raise AuthenticationError(f"Invalid token: {exc}")
    return UserClaims(**payload)


# webhooks/signature_validator.py
def validate_webhook_jwt(token: str) -> WebhookClaims:
    try:
        payload = jwt.decode(token, WEBHOOK_SECRET, algorithms=["HS256"])
    except jwt.ExpiredSignatureError:
        raise WebhookValidationError("Webhook token expired")
    except jwt.InvalidTokenError as exc:
        raise WebhookValidationError(f"Invalid webhook token: {exc}")
    return WebhookClaims(**payload)
“But that’s identical code!” — the reviewer will shout.
No. These are two different security contexts with different secrets, different exception types, and different claims models. Merging them into one function validate_any_jwt(token, secret, claims_class, error_class) creates cross-cutting dependency that someone will later extend with “just one” asymmetric-crypto flag for webhooks, then “just one” custom claim for user JWTs, and a year later have a function with 12 parameters.
Two modules, two contexts, two responsibilities. The identical skeleton is just a characteristic of the JWT signature, not a reason to couple.
Where a Shared Source of Knowledge Helps
Separating responsibilities does not justify inconsistent copies of the same rule. A shared source of knowledge is particularly useful in these areas:
- Database schema — migrations should describe changes clearly. DTOs and domain models need not mirror tables; generation helps where they represent the same contract.
- API contracts between services — OpenAPI/Protobuf/GraphQL schema as single source of truth, both endpoints generated from the same file.
- Configuration constants — no magic string “production” in 47 places, one
Environment.PRODUCTION. - Rules derived from regulations — identify the source and version of each rule. Different countries, effective periods and contexts can require distinct rules.
These are cases of real knowledge duplication — violations of the original DRY definition from Pragmatic Programmer.
Conclusion: Craftsmanship, Not Ideology
Software engineering isn’t about maximizing the “lines without repetition” metric. It’s about minimizing the long-term cost of change. Sometimes that cost is lower under duplication, sometimes under abstraction — and it’s the engineer’s job to distinguish, not the linter’s.
Two rules to remember when you next see “similar code”:
- Rule of Three — treat another occurrence as a chance to inspect the pattern, not an automatic refactoring instruction.
- Wrong abstraction costs more than duplication — because abstraction is harder to reverse than copying 30 lines.
Engineers who understand this design systems that evolve. Engineers who chase DRY as dogma design systems that calcify — until the abstraction debt forces a rewrite from scratch.
The line between real and apparent duplication is clearest when you read other people’s code faster than you wrote your own — because that’s when you judge which abstractions actually carry their weight. The same skepticism toward dogma pays off in debugging, where a hypothesis beats a reflex.
References: DRY in The Pragmatic Programmer, Sandi Metz: The Wrong Abstraction.